
Loading page
Inspect attention weights across encoder and decoder layers.
The attention panel shows exactly what a chosen attention head looked at while producing its output — one layer, one head, at a time.
Attention is the mechanism transformer models use to decide which parts of their input matter when producing each output. Every layer has several heads, and each head assigns a weight between every pair of positions. Plotting those weights for one layer and one head shows which words the model tied to which stretch of audio.
Attention extraction is available for Whisper and custom models only. It is not available for wav2vec2 — wav2vec2 is a CTC classifier without the encoder-decoder attention structure this panel visualizes.
Different heads specialize differently — some track local acoustic continuity, others track longer-range structure. There's no single "right" head to look at; the point of exposing both indices is to let you sweep across layers and heads and compare.
For the chosen layer and head, the panel transcribes the clip, gets word-level start and end times, and pairs each transcript word with the words it attends to. Each pair carries its attention weight plus the time interval of both words, which is how weights get placed on the audio timeline.
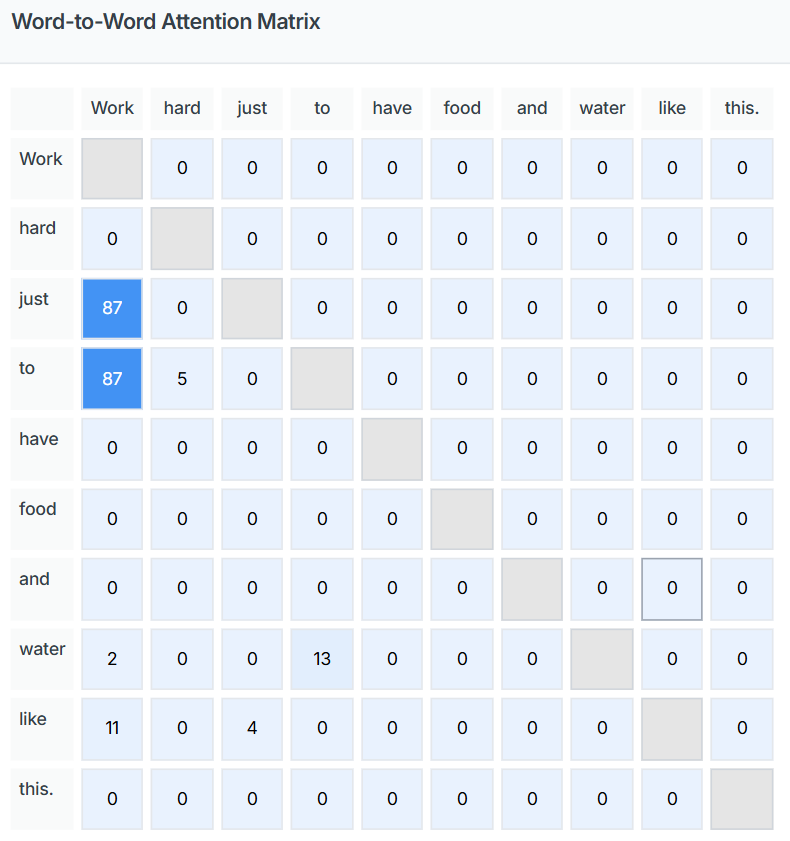
Matrix view
ATTENTION_FORCE_CPUAttention extraction on GPU can trigger a Triton segfault in the underlying
kernel. ATTENTION_FORCE_CPU (default true) works around this by forcing
attention computation onto CPU regardless of the worker's normal device
selection. Leave it on unless you've specifically verified GPU attention
extraction is stable on your hardware — turning it off trades a rare crash
for slightly faster runs.