
Loading page
A decoder-only, position-resolved lens over Whisper's decoder layers.
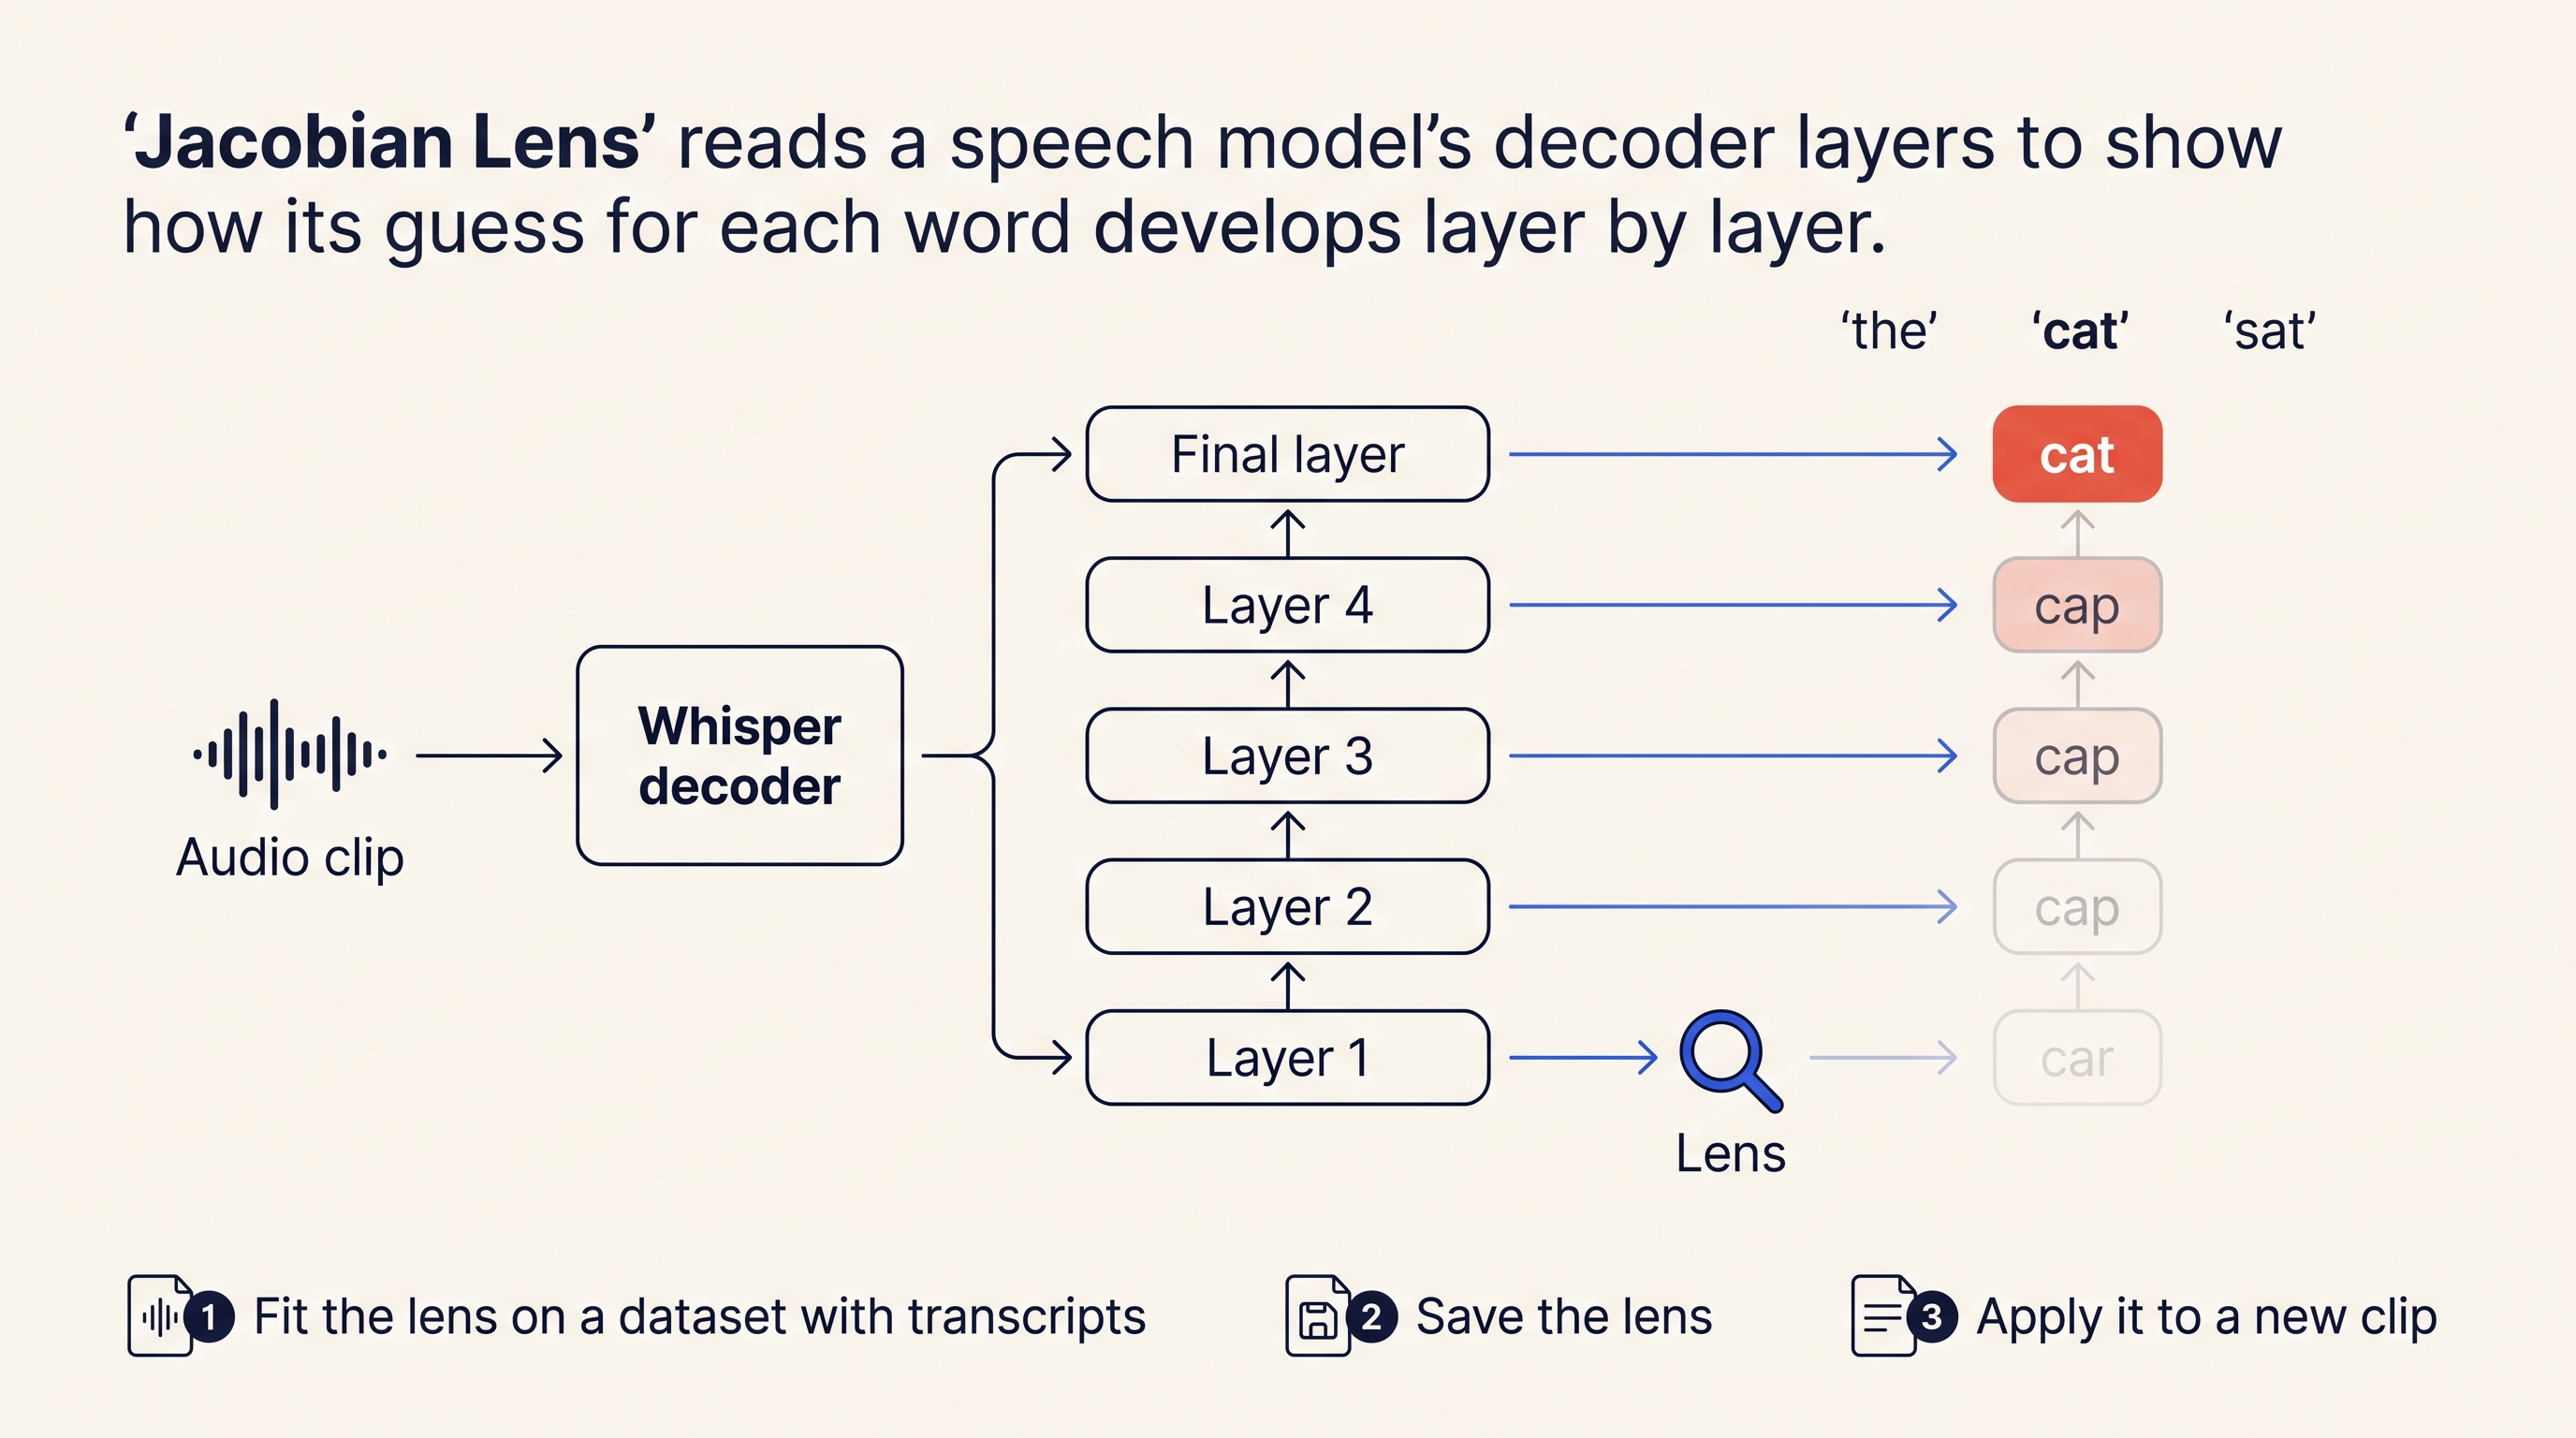
Jacobian Lens is a decoder-only, position-resolved lens over Whisper's decoder layers — it learns a mapping you can then apply to new clips to see how a decoder layer's representation relates to the tokens it eventually produces, position by position.
Jacobian Lens reads Whisper's decoder layers as if they were making predictions themselves. At each token position, it maps a layer's intermediate representation onto the vocabulary, so you can see how the model's guess develops layer by layer before it settles on the final token.
jacobian_lens_fit — fits a new lens from a dataset of samples.
Requires 2 to 1000 samples, each clip ≤ 60 seconds (max_audio_seconds
defaults to 30), and a dataset
or manifest that includes a transcript (the lens is fit against
known text, not raw audio alone).jacobian_lens_apply — applies an already-fitted lens to a clip.
Takes top_k (how many top results to return), an optional
transcript, and max_new_tokens (8–256, default 64).Fitting a lens has its own dedicated page in the app: /j-lens, called
the J-Lens Lab. It's a 3-step flow:
Choose the Whisper checkpoint and the dataset (with transcripts) you'll fit against.
Choose which samples from that dataset — within the 2–1000 range — go into the fit.
Submit the fit job and wait for it to complete; the result is a saved lens you can apply to new clips afterward.
Once fit, a lens is saved and shows up in a saved lenses list, ready to
apply to new clips via jacobian_lens_apply without re-fitting.
To remove one:
curl -X DELETE http://localhost:8000/jobs/jacobian-lenses/{lens_id} \
  --cookie "sid=<your session cookie>"